Z-Image Base: The 6B S3-DiT Foundation for Ultimate Photorealism & LoRAs
Discover the undistilled 6-billion-parameter foundation checkpoint behind Alibaba Tongyi-MAI's Z-Image ecosystem. Engineered for full classifier-free guidance (CFG), negative prompt precision, museum-grade textures, and custom community LoRA & ControlNet training.
Ultra-HD AI Image Playground
Generate high-fidelity 4K visuals with professional-grade instruction following and lightning-fast rendering.
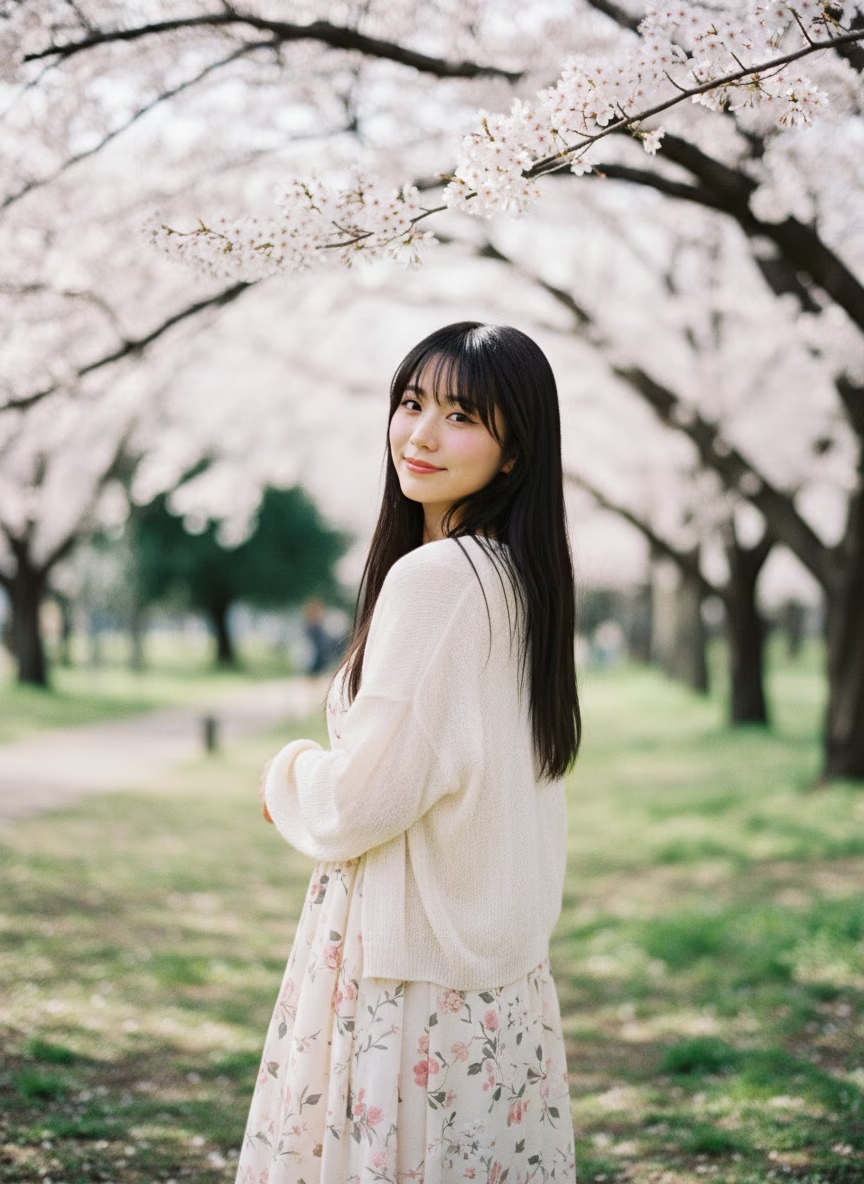
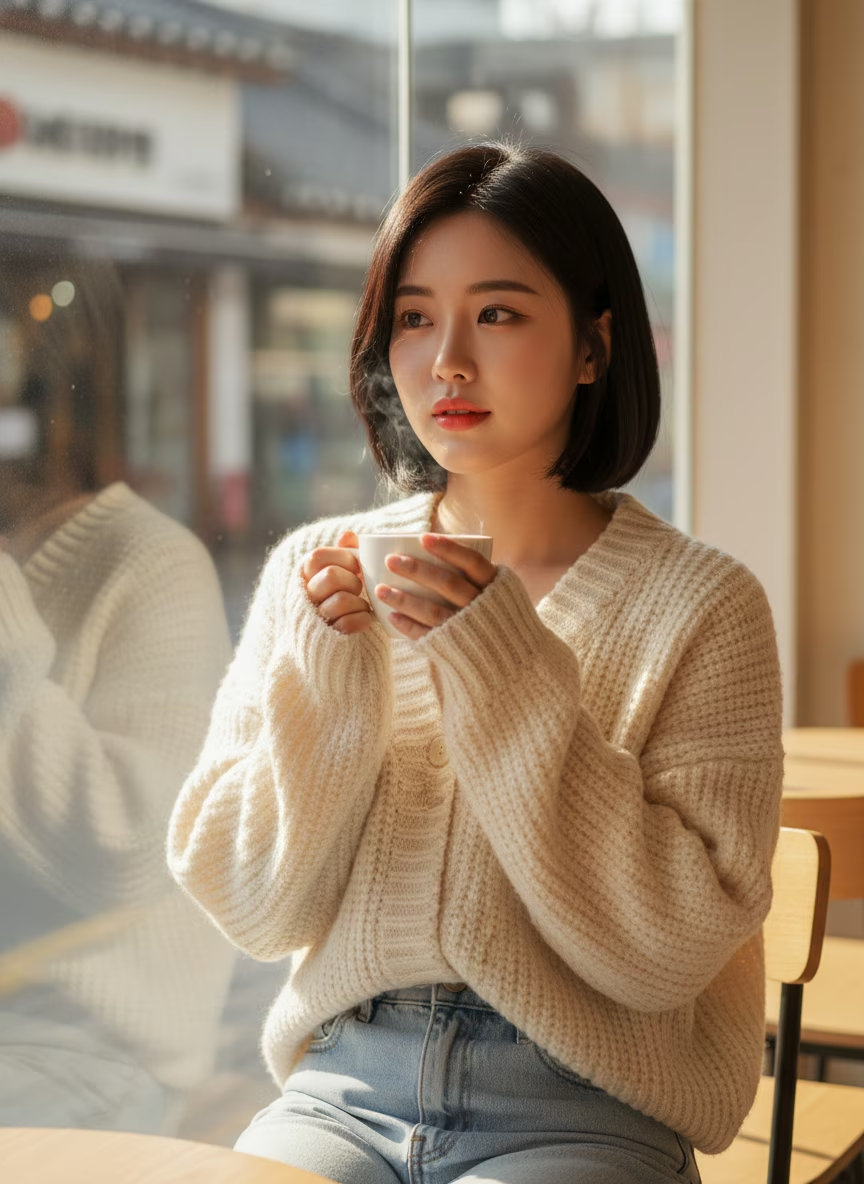
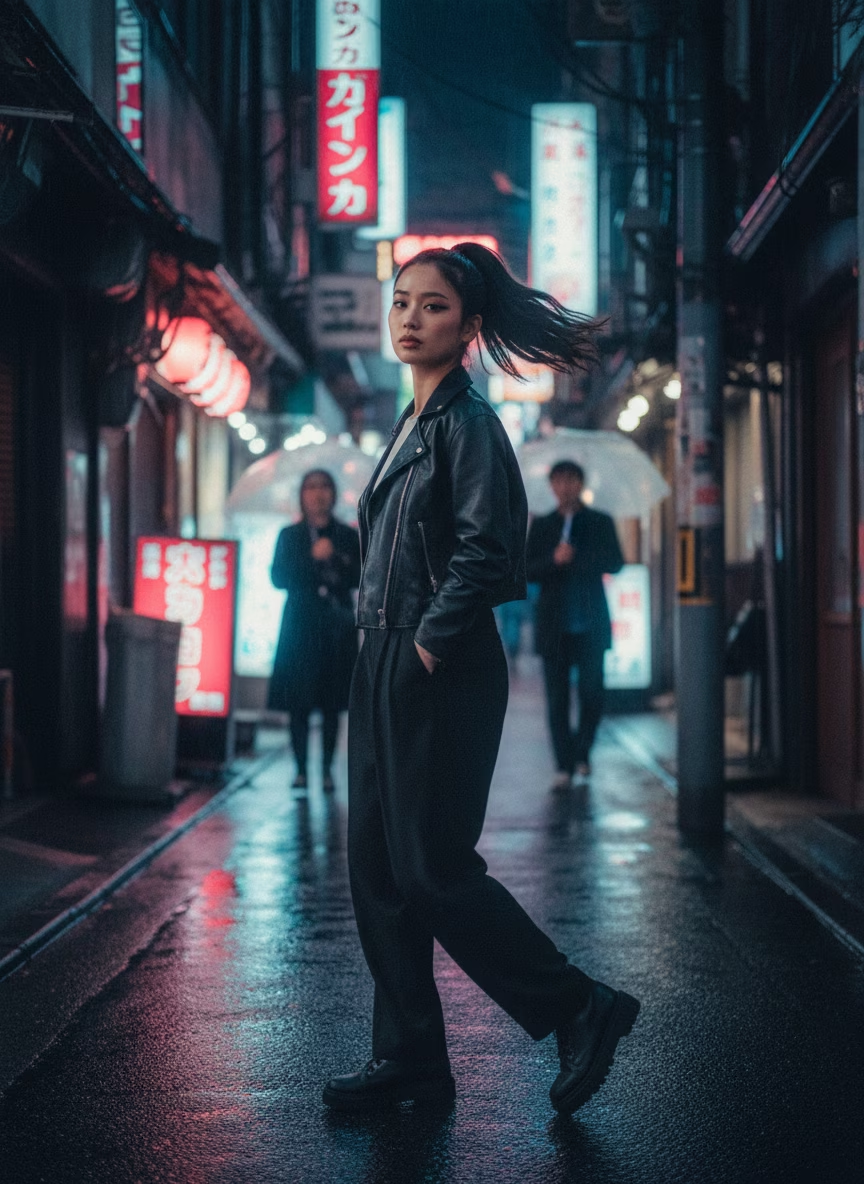
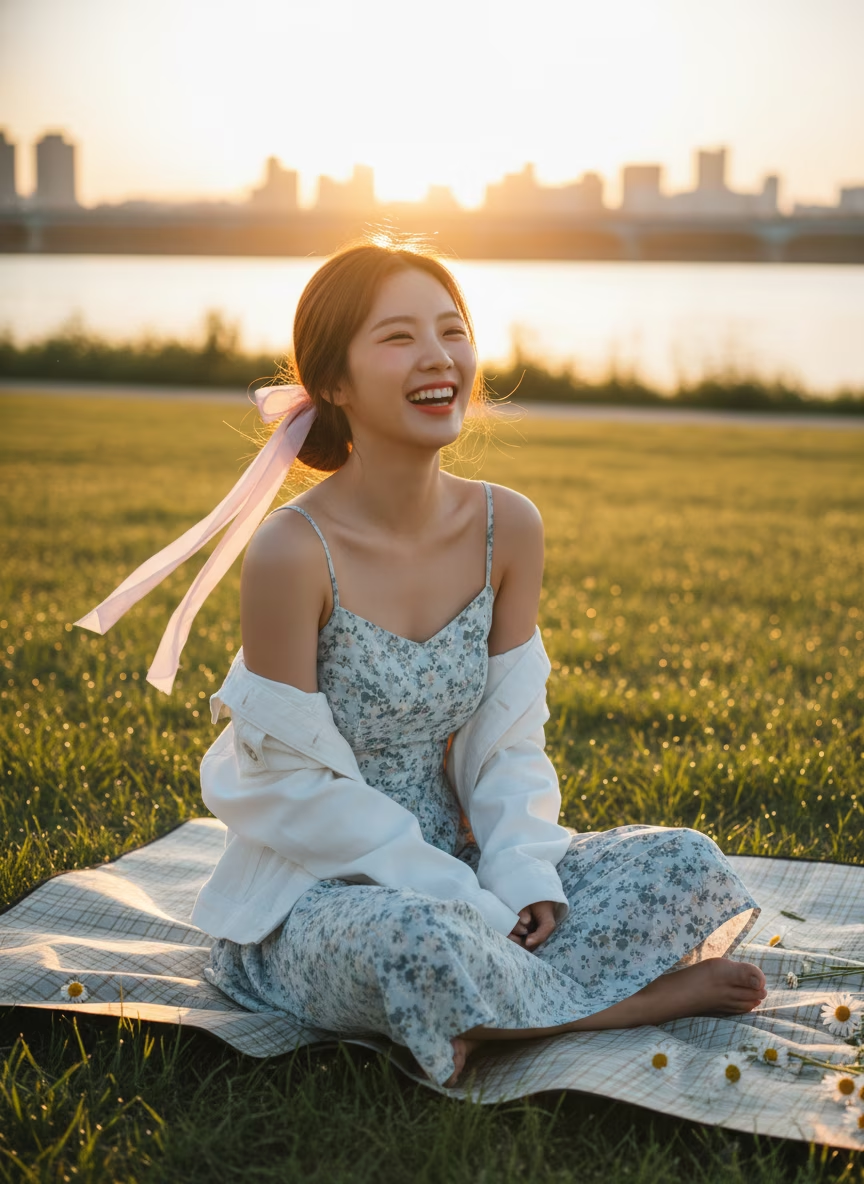
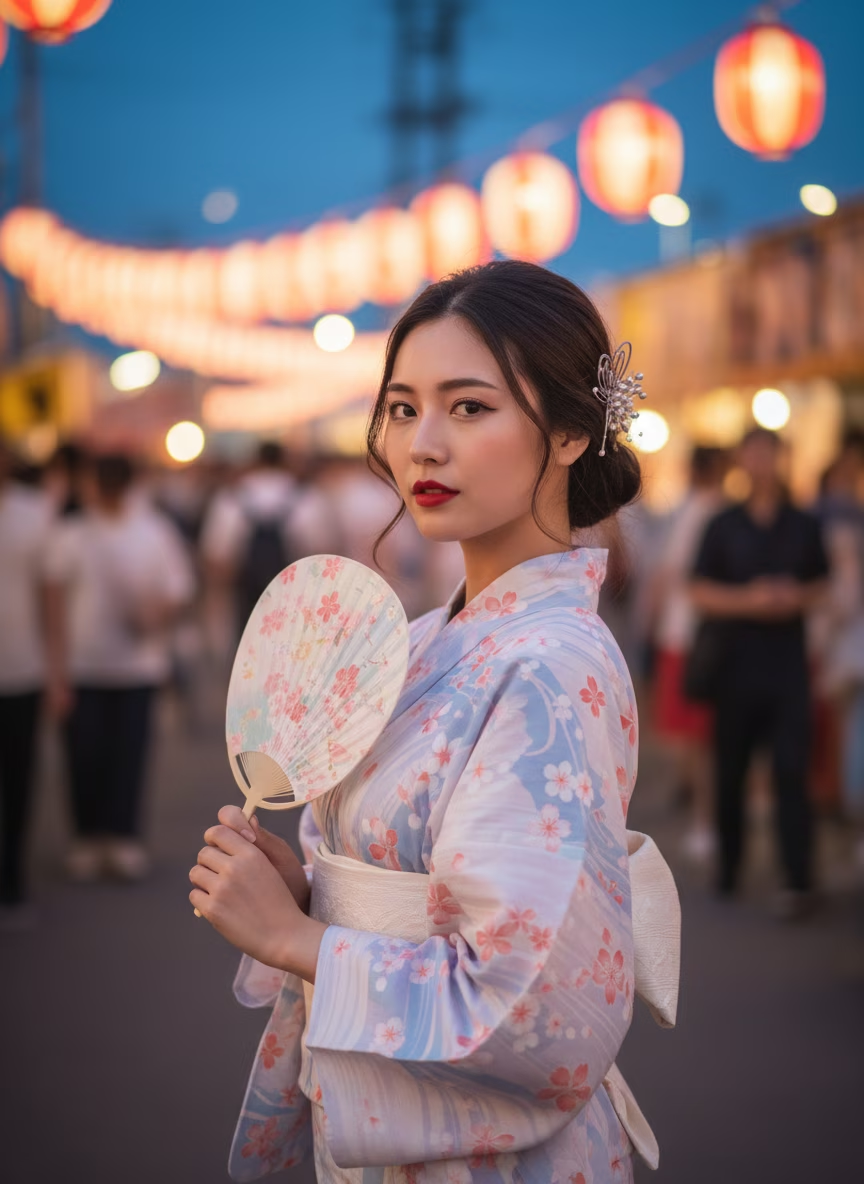
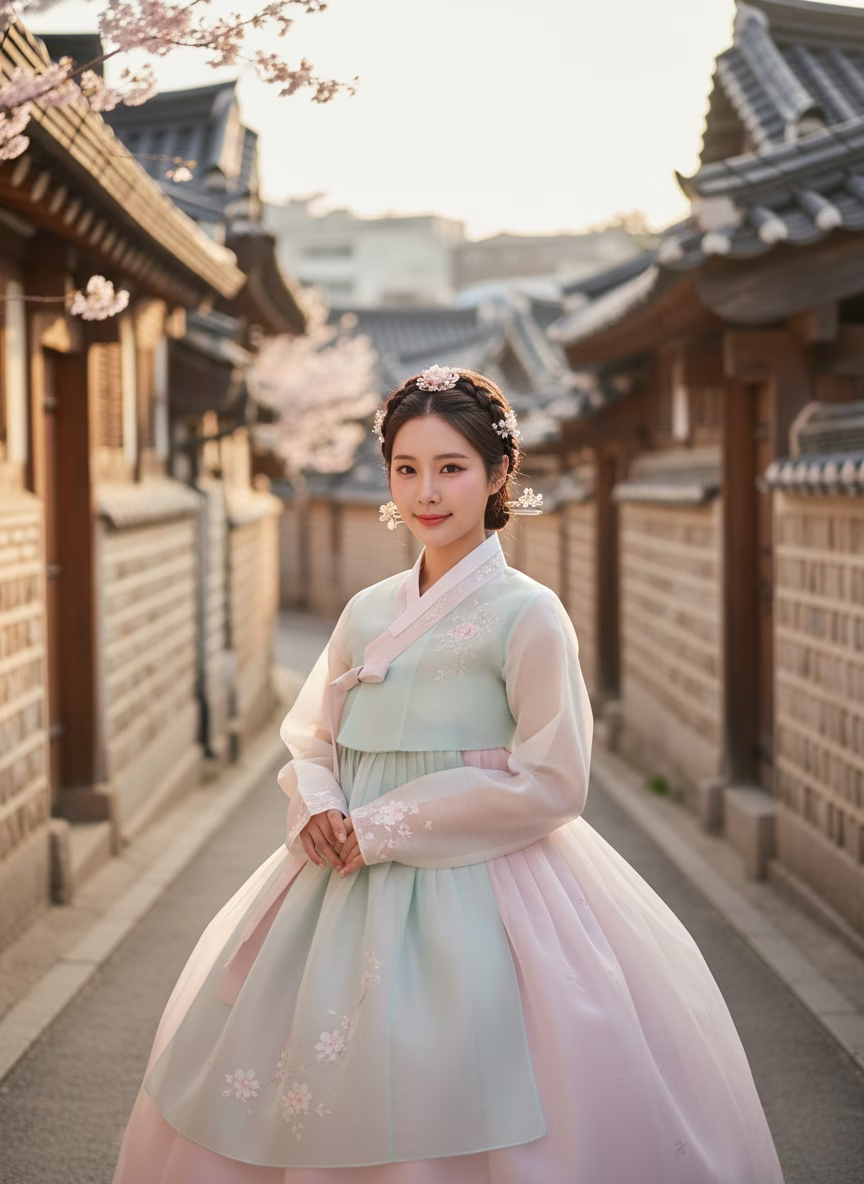
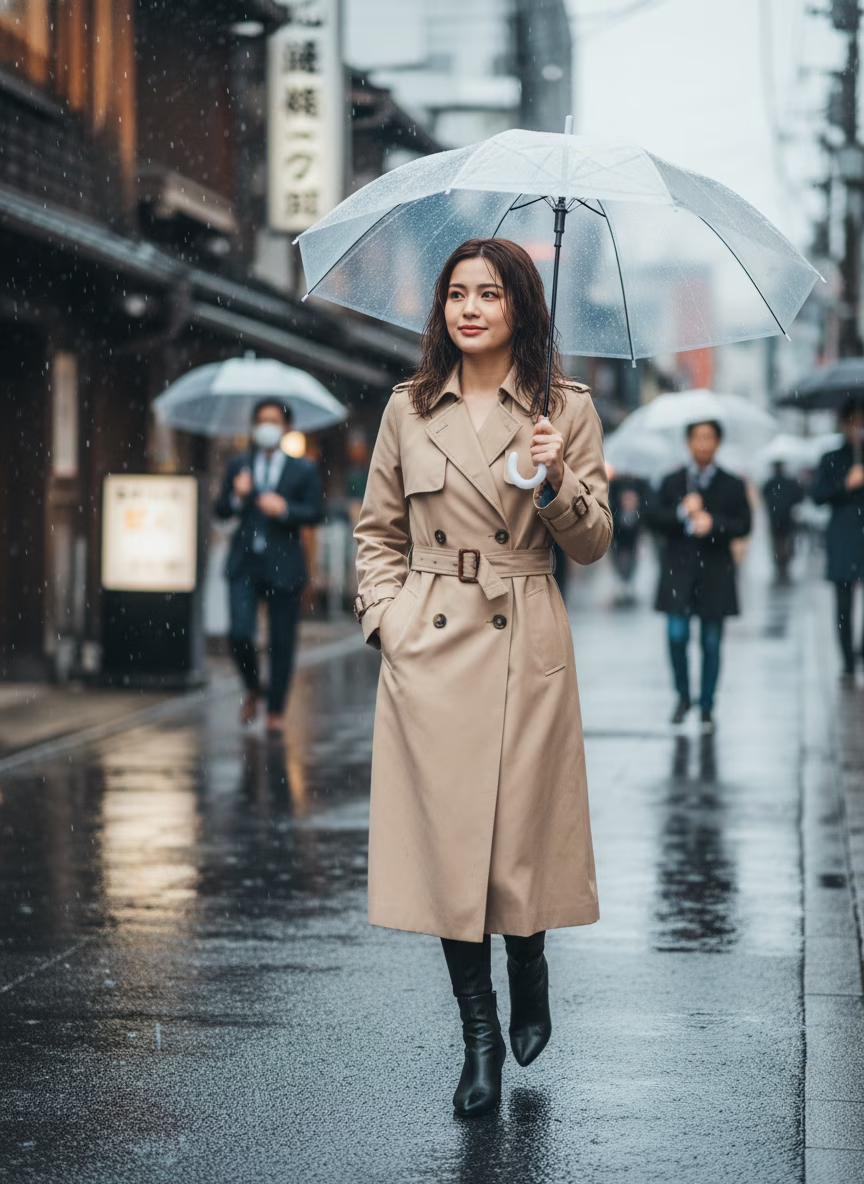


Why Z-Image Base Matters for Serious Creators & Developers
While Z-Image Turbo dominates sub-second 8-step generation, step-distilled models compress latent diversity and make downstream LoRA training harder. Alibaba Tongyi-MAI released the undistilled Z-Image Base (Tongyi-MAI/Z-Image) checkpoint specifically to unlock full multi-step denoising diversity, granular Classifier-Free Guidance (CFG), negative prompt steering, and clean fine-tuning convergence.
Maximum Creative Diversity
Without step-distillation mode collapse, Z-Image Base produces wider compositional variety across seeds—ideal for art direction, concept exploration, and high-fashion photography.
Full CFG & Negative Prompt Control
Supports standard multi-step sampling (typically 28–50 NFEs with CFG 3.5–5.0), letting artists sculpt lighting, suppress unwanted artifacts, and dial in exact stylistic balance.
Built for LoRA & ControlNet Training
Because gradients remain undistilled, training character LoRAs, product consistency adapters, and regional ControlNets on 6B Z-Image Base converges faster and requires half the VRAM of 12B FLUX.1-dev.
Bilingual Semantic Foundation
Shares the exact same bilingual English and Chinese text-image token stream, enabling fine-tuners to build specialized typography, anime, architectural, and e-commerce checkpoints.
When to Choose Z-Image Base vs Z-Image Turbo
Understanding how Z-Image Base and Z-Image Turbo complement each other helps studios pick the exact right tool for every stage of production.
How to Prototype Z-Image Workflows on z-img.net
Combine instant cloud ideation with foundation-grade prompt engineering:
1. Sign In to Your Cloud Studio
Access z-img.net from any browser to test prompts across Z-Image and frontier multimodal generators without downloading 12GB+ safetensors files first.
2. Test Bilingual Prompts & Curated Templates
Load proven portrait, architectural, and typography templates from our carousel to study how S3-DiT responds to camera, lighting, and quoted text tokens.
3. Export 4K Renders or Scale Locally
Download ready-to-use high-resolution visuals directly from the cloud, or follow our local deployment docs to run custom Z-Image Base + LoRA pipelines.
Z-Image Base Architectural Highlights
Engineered by Alibaba Tongyi Lab for open-source extensibility and commercial reliability.
6B Single-Stream DiT (S3-DiT)
Concatenates text, visual semantic, and VAE tokens into one unified transformer stream for maximal parameter efficiency.
Native Negative Prompt Support
Full classifier-free guidance lets you explicitly steer away from unwanted styles, colors, or anatomical errors.
Half the Footprint of FLUX.1-dev
6 billion parameters vs 12 billion cuts VRAM consumption and LoRA training time dramatically on 16GB–24GB GPUs.
Bilingual Token Alignment
First-class Chinese and English comprehension for global creative teams and cross-border brands.
ComfyUI & Diffusers Native
Supported out of the box in Hugging Face Diffusers, ModelScope, and standard ComfyUI nodes.
Permissive Apache 2.0 License
Unlike non-commercial dev weights from competing labs, Z-Image allows unrestricted commercial fine-tuning and deployment.
Z-Image Base Foundation Specs
Core specifications of the undistilled Z-Image 6B checkpoint.
6B Params Undistilled S3-DiT Foundation
28–50 Steps Full CFG Denoising Precision
Apache 2.0 Commercial & LoRA Fine-Tune Ready
Z-Image Base Frequently Asked Questions
Key differences between Z-Image Base, Z-Image Turbo, and FLUX.1-dev.