Z-Image: 8-Step Photorealistic AI Image Generator with Bilingual Text
Powered by Alibaba Tongyi-MAI's 6B Scalable Single-Stream Diffusion Transformer (S3-DiT). Generate 4K studio-grade photography, posters, and crisp English & Chinese typography in under a second—sign in for free starter cloud GPU credits.
Ultra-HD AI Image Playground
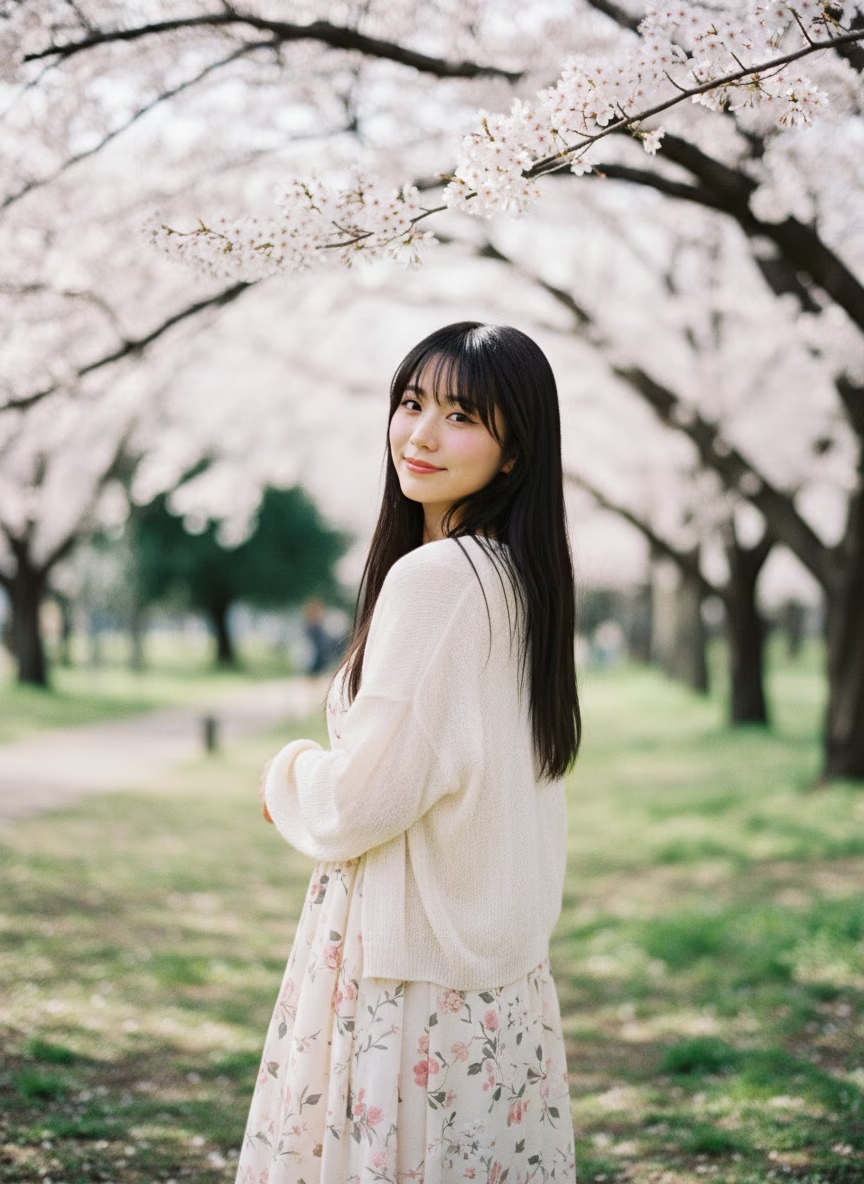
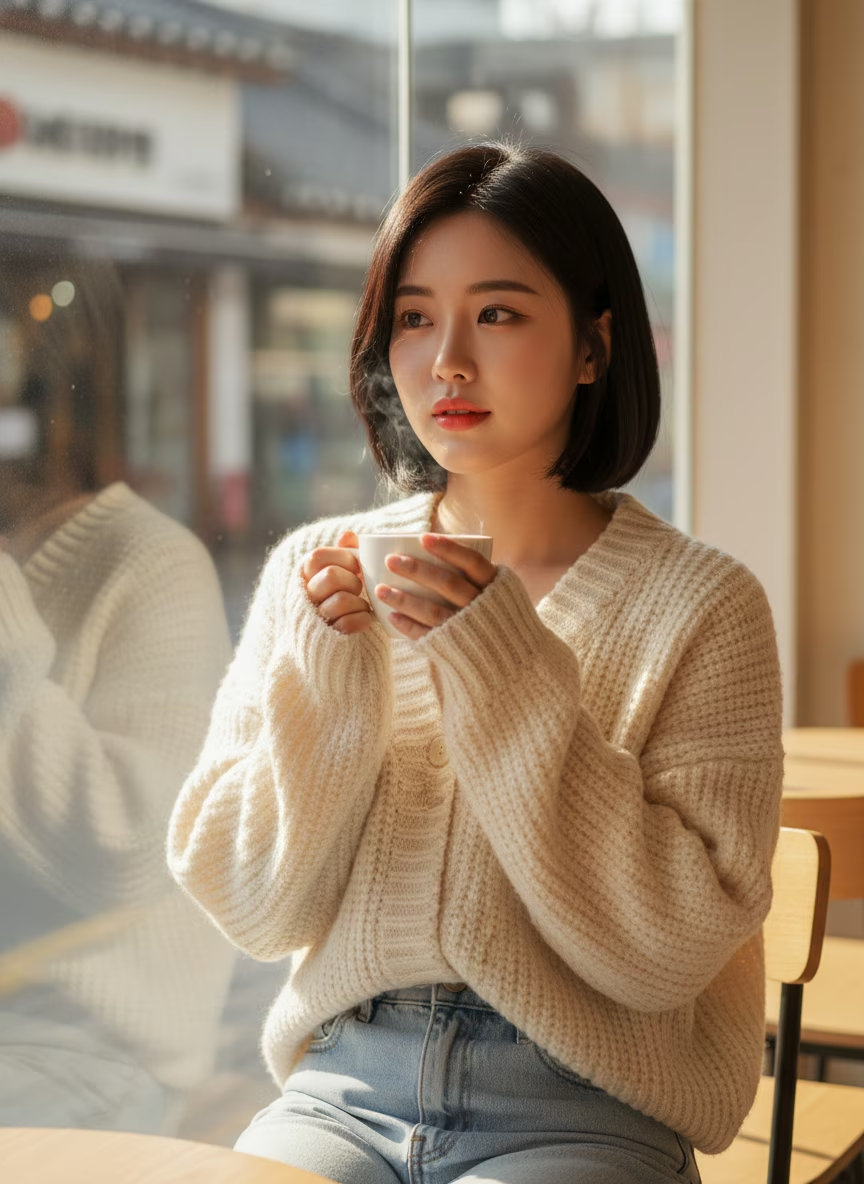
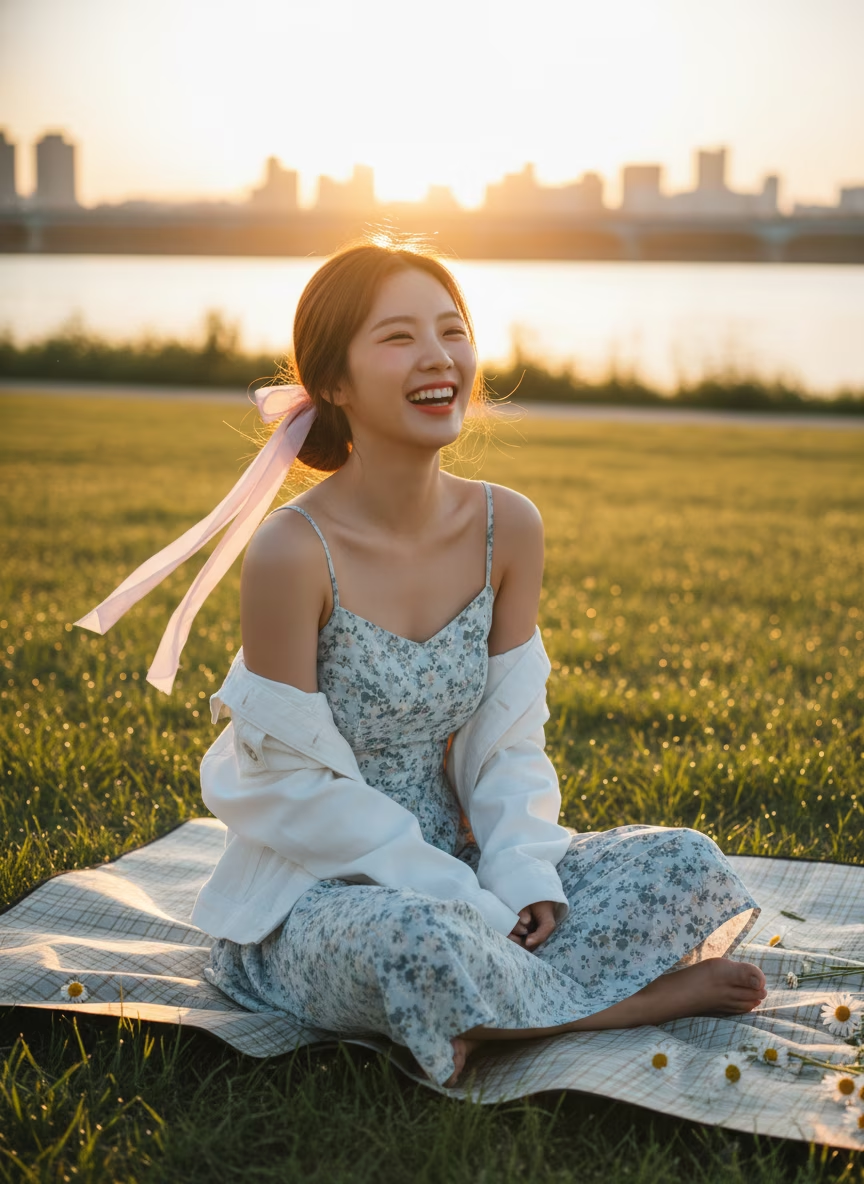
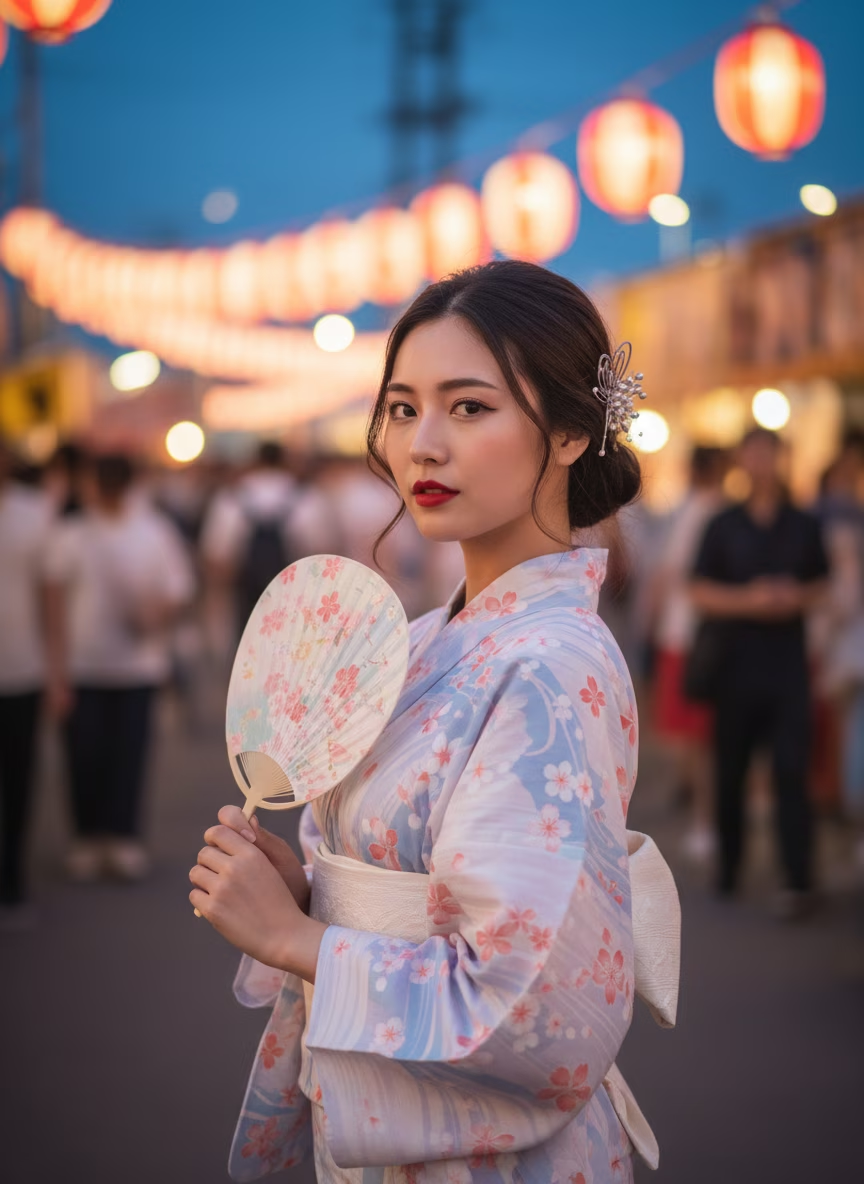
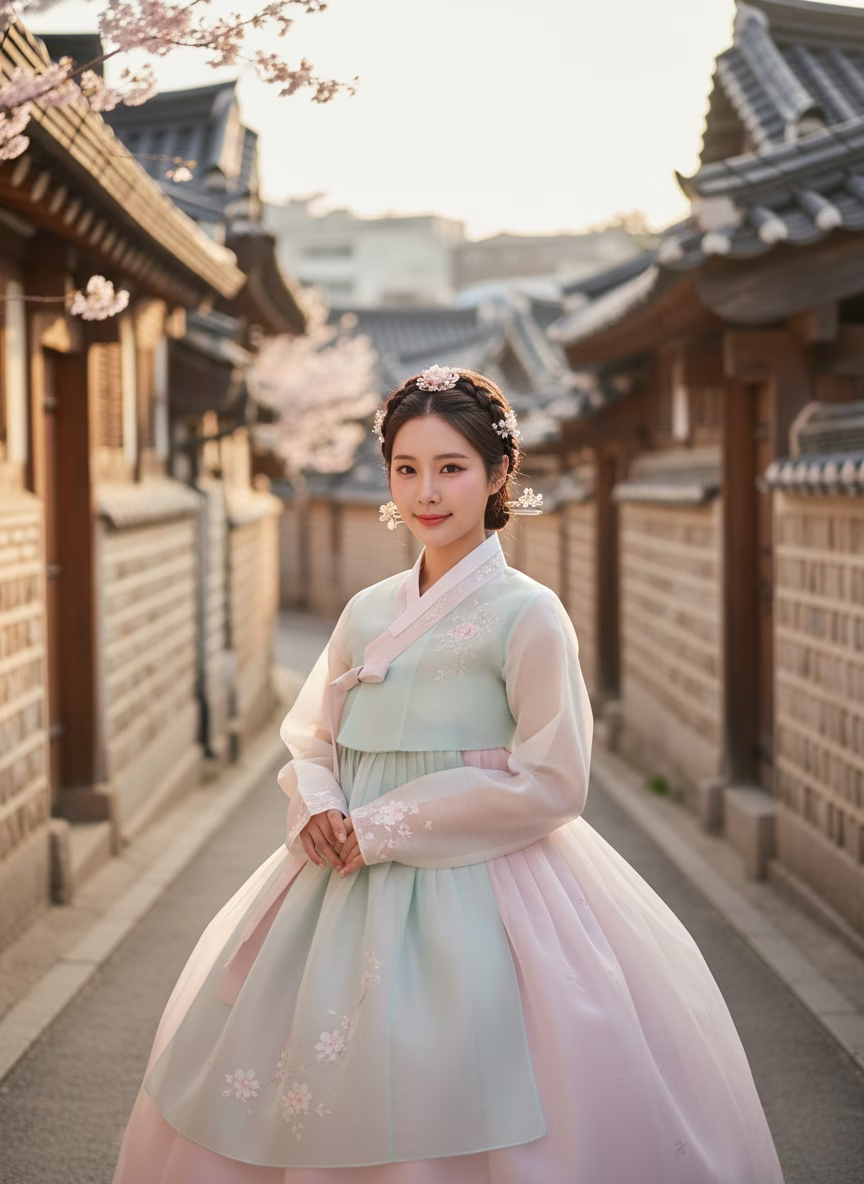
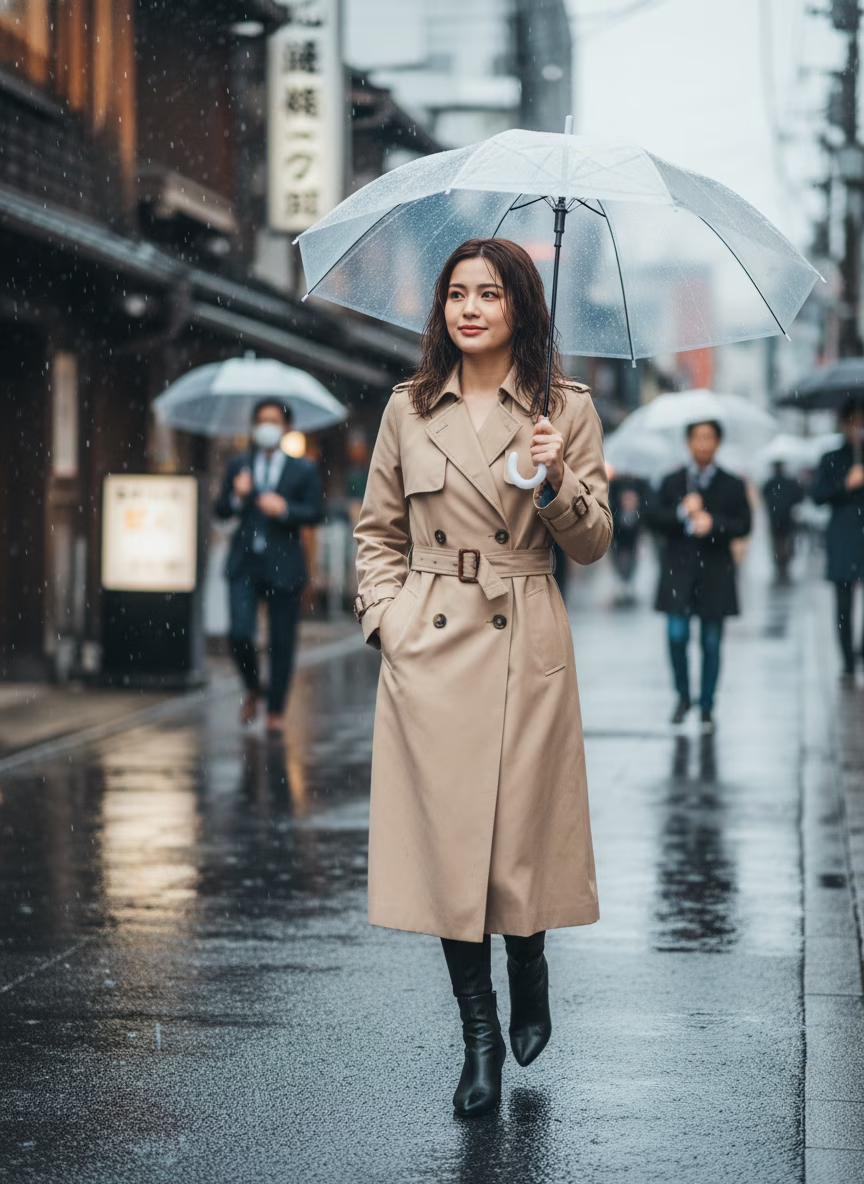
Generate high-fidelity 4K visuals with professional-grade instruction following and lightning-fast rendering.


Why Choose Z-Image AI?
Developed by Alibaba's Tongyi Lab (Tongyi-MAI), Z-Image redefines open-source text-to-image efficiency. By unifying text tokens, visual semantic tokens, and image VAE latents inside a single 6-billion-parameter Scalable Single-Stream Diffusion Transformer (S3-DiT), Z-Image matches or surpasses 12B–32B commercial models like FLUX.1 and Midjourney while running up to 10x faster.
8-Step Z-Image Turbo Speed
Through Decoupled-DMD step distillation and RL post-training, Z-Image Turbo synthesizes crisp photorealistic images in just 8 Number of Function Evaluations (NFEs), achieving sub-second latency on cloud H800/A100 GPUs.
Native Bilingual Typography
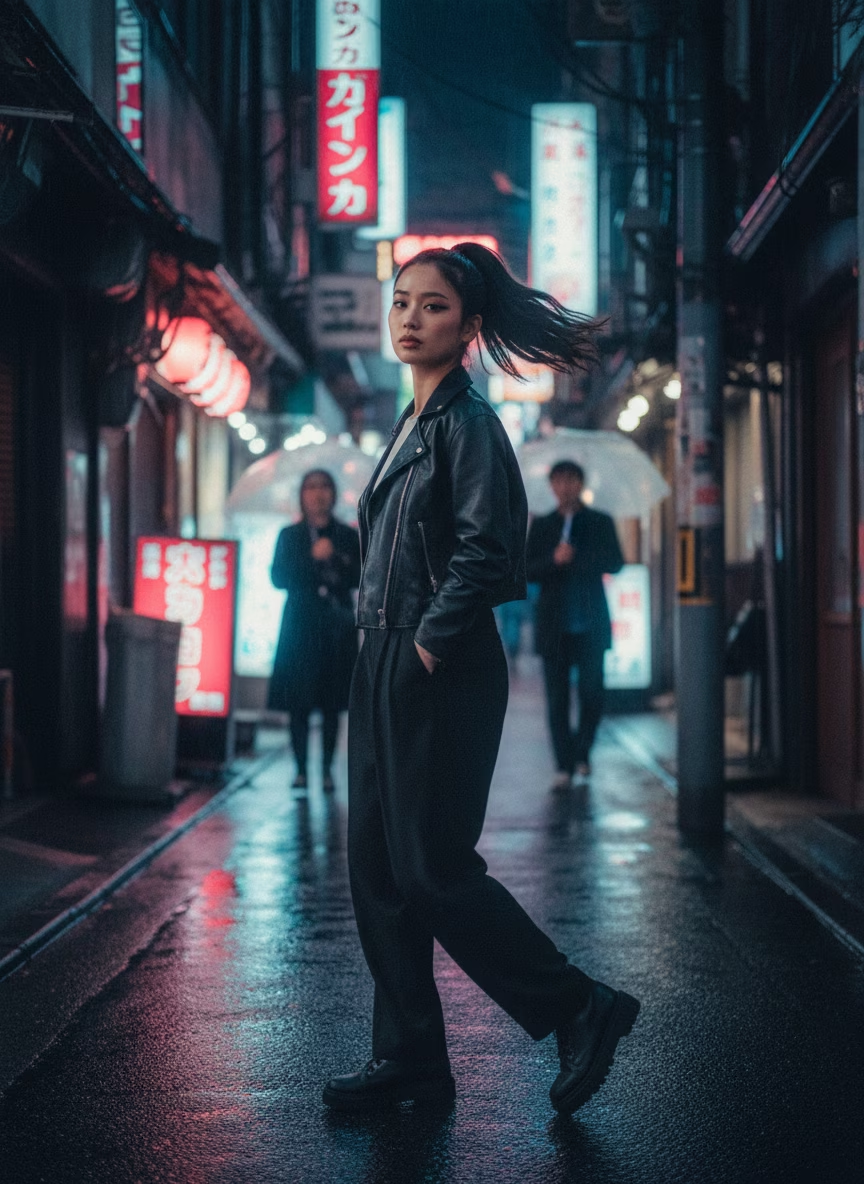
Unlike Western-centric diffusion models that scramble Asian glyphs, Z-Image natively understands complex English and Chinese (Hanzi) prompts and renders sharp, accurate bilingual text directly onto posters, signage, and packaging.
Compact 6B S3-DiT Efficiency
Built on a parameter-efficient 6B Single-Stream DiT backbone rather than bloated dual-stream architectures, Z-Image fits comfortably within 16GB consumer VRAM locally—or runs instantaneously in our hosted browser studio.
Apache 2.0 Commercial Freedom
Released under the permissive Apache 2.0 open-source license by Tongyi-MAI, Z-Image empowers e-commerce brands, ad agencies, indie game studios, and developers to deploy generated artwork commercially with confidence.
Z-Image Capabilities Across Creative Workflows
From instant e-commerce product campaigns and bilingual brand posters to museum-grade portrait photography and ComfyUI pipelines, the Z-Image model family handles demanding visual production end to end.
How to Generate Art with Z-Image Online
Go from raw text prompt to 4K commercial artwork in three streamlined steps:
1. Sign In & Select Z-Image Model
Log in to your z-img.net workspace to claim starter cloud credits, then choose Z-Image Turbo for ultra-fast 8-step generation or switch across our multi-model lineup including Nano Banana 2 and GPT Image 2.
2. Craft Your Bilingual Prompt & Aspect Ratio
Describe subject, camera lens, lighting, and any exact text enclosed in quotation marks (supports both English and Chinese prompts natively). Pick from 15 aspect ratios including 1:1, 16:9, 9:16, 3:4, and panoramic banners.
3. Render in Seconds & Download 4K Assets
Let our cloud GPUs execute Z-Image's S3-DiT pipeline in seconds. Preview, iterate on your favorite prompt templates, and export high-resolution watermark-free visuals ready for commercial publishing.
Z-Image Studio Features & Model Advantages
Engineered around Alibaba Tongyi-MAI's S3-DiT research to give creators speed, typographic accuracy, and total layout control.
Native EN/ZH Prompt Reasoning
Powered by Qwen-aligned text encoding to interpret idioms, cultural aesthetics, spatial layouts, and multi-object instructions in English and Chinese without translation loss.
15 Flexible Aspect Ratios
Generate native compositions in 1:1 square, 9:16 vertical reels, 16:9 cinema widescreen, 3:4 e-commerce cards, and ultra-wide 21:9 or 4:1 banners.
One-Click Curated Prompt Templates
Jumpstart creation with dozens of tested Z-Image photography, portrait, cyberpunk, qipao, and product design templates—load any prompt with one click.
Z-Image Turbo & Base Synergy
Understand when to use 8-step distilled Z-Image Turbo for rapid ideation versus undistilled Z-Image Base for fine-grained textures and custom LoRA workflows.
Cloud Task History & Management
Every signed-in session securely tracks your recent image and video tasks so you can revisit prompts, compare model outputs, and batch-download assets.
Private & Commercial-Safe Workspace
Your private prompts and commercial brand assets are never sold or used to train third-party foundation weights.
Z-Image S3-DiT Technical Specifications
Key architectural benchmarks behind Alibaba Tongyi-MAI's Z-Image Turbo foundation model.
8 NFEs Turbo Distillation Steps (Sub-Second Latency)
6B Params Scalable Single-Stream DiT (S3-DiT)
Apache 2.0 Open-Source Commercial License
Stay Updated on Z-Image Ecosystem
Receive curated Z-Image Turbo prompt formulas, ComfyUI workflows, and new model releases.
Z-Image Frequently Asked Questions
Everything you need to know about Z-Image architecture, Z-Image Turbo vs Base, bilingual text rendering, and online cloud generation.